AI data centers are rewriting the rules of power infrastructure design. A rack of conventional CPU servers once drew around 10 kW. A fully configured NVIDIA GB200 NVL72 rack now draws roughly 120 kW, and roadmaps for 2026 already point toward racks approaching 600 kW. At the same time, the International Energy Agency expects global data center electricity demand to more than double to around 945 TWh by 2030, with AI as the single largest driver. For operators, this shifts the core question. It is no longer "do we have enough total capacity?" but "can our power architecture deliver clean, redundant, and visible power from the utility connection all the way to each high-density GPU rack?"
How Much Power Does an AI Rack Actually Need?
"Significantly more power" is not a planning number. The honest answer is that AI rack power depends on the GPU platform, the redundancy target, and the cooling method, but the public reference points are now concrete enough to design against.

- General-purpose CPU rack: up to about 12 kW.
- Air-cooled H100-class rack: roughly 40 kW, near the practical ceiling for air.
- NVIDIA GB200 NVL72: roughly 120 kW per rack, and around 132 kW fully configured, delivered through multiple power shelves on 415–480 V three-phase feeds into a DC busbar.
- Next generation (2026 roadmap): rack-scale systems projected toward 240–600 kW.
For context on how extreme this is: the Uptime Institute's 2025 global survey puts the average rack density at roughly 9 kW, and more than 80% of operators still report no racks above 30 kW. Fewer than 1% of operators run racks above 100 kW, and those that do are mostly running traditional high-performance computing. A single GB200 pod, in other words, asks a building to do something that 99% of the industry has never done. That gap, not raw megawatts, is where most AI power projects get into trouble.
Why AI Workloads Break Legacy Power Assumptions
AI training, inference, and HPC depend on dense clusters of accelerators, servers, storage, and a heavy mesh of high-speed fiber networking. These systems do not behave like conventional enterprise IT. A traditional rack was planned around a steady draw; an AI rack pushes far higher peak power and swings its consumption sharply as GPUs ramp together. When dozens of racks do this at the same moment, the effect moves past the cabinet and reaches branch circuits, rack PDUs, distribution paths, UPS modules, and the cooling plant.
That is why AI-ready power has to be treated as one end-to-end system. Utility input, switchgear, UPS, distribution, busway, rack PDU, monitoring, and cooling are not separate procurement line items here. They are a single chain, and the chain is only as deployable as its weakest link.

The Critical AI Data Center Power Challenges
1. Rack Power Density Outpaces Legacy Infrastructure
The most visible challenge is that floor space and electrical capacity no longer line up. A room rated for 8–10 kW per cabinet cannot host a 120 kW rack just because the tile is empty.
What this means in practice: in a retrofit, the first wall is rarely total utility capacity. It is branch-circuit count, busway ampacity, floor loading (a GB200-class rack exceeds 1,300 kg), or simply door and aisle clearance. Many rooms run out of deliverable amps per cabinet, and out of structural headroom, long before the hall runs out of megawatts. Plan capacity at both the rack level and the cluster level, and confirm how many usable amps you can actually land at each cabinet.
2. Dynamic GPU Loads Stress UPS Transient Response
AI loads are bursty and synchronized. A collective all-reduce step or a checkpoint write can move a cluster's draw by tens of percent in milliseconds, then drop it again.
What this means in practice: on a double-conversion UPS, those swings appear as load steps the inverter and static bypass have to ride through cleanly. Under-coordinated breakers can nuisance-trip on the upswing and kill a multi-day training run; poorly shared parallel UPS modules can fight each other during the transient. Specify UPS and protection for fast load steps and verify breaker coordination against the real load profile, not the nameplate average. On-site battery storage is increasingly used specifically to absorb these swings at facility scale.
3. High-Density Power Distribution for GPU Racks
A fixed distribution path that worked for static enterprise loads rarely supports dense GPU rows, phased growth, and A/B redundant feeds at the same time.
What this means in practice: on A/B feeds, the real test is the failover case. When one path drops, the surviving path must carry the full rack load without exceeding its breakers or starving neighboring cabinets. Sizing each feed for N capacity instead of the redundant load is a common and expensive mistake. Overhead busway often makes it easier to add or relocate capacity than fixed whips, but the right choice depends on density, room layout, and maintenance strategy.
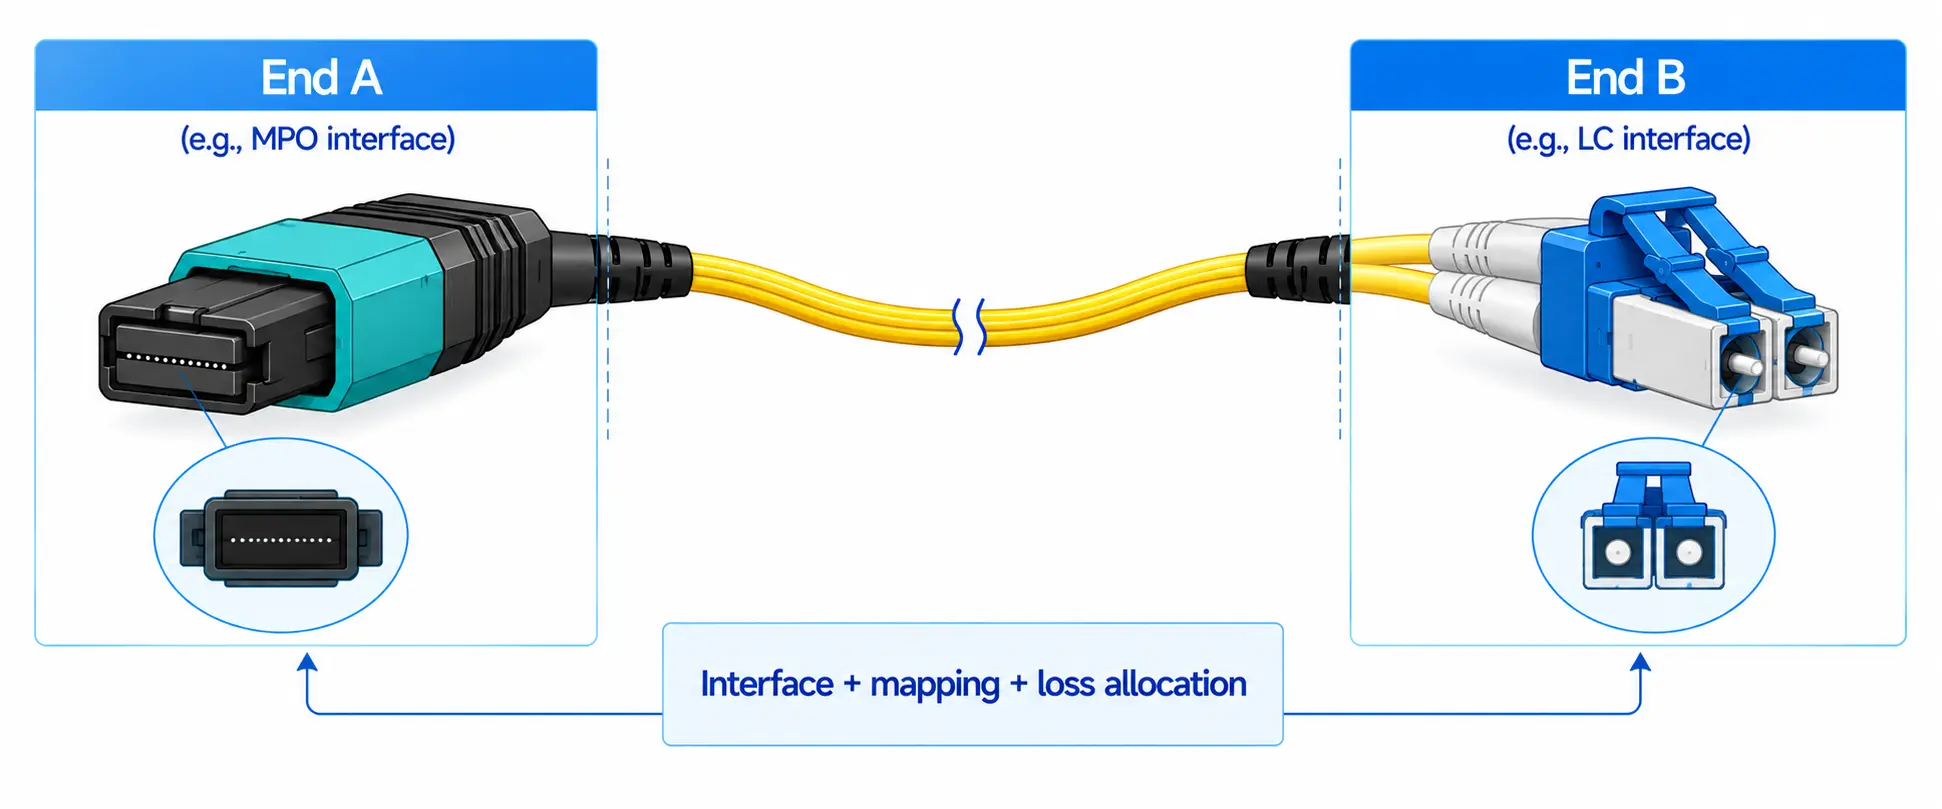
Distribution is also where cabling competes with power for the same trays and conduits. A single 120 kW pod terminates hundreds of fiber connections to leaf and spine switches, and that fiber shares routing and airflow paths with the power feeds. In dense rows, MPO/MTP trunk cabling keeps the connection count and bulk manageable so it does not block airflow or service access. Reach matters too: short GPU-to-leaf links typically run on multimode, while spine and campus links move to single-mode (OS2) fiber for the longer distances.
4. Power Quality Becomes a Business Continuity Issue
In AI facilities, power quality is not just an electrical concern. It directly affects uptime, hardware life, and whether a training run survives.
What this means in practice: high-crest-factor switch-mode loads and unbalanced single-phase tap-offs push neutral currents, harmonic distortion, and phase imbalance upward. Left unmonitored, an imbalance usually shows up first as a hot connection or a tripped branch, not as a tidy dashboard alert. Because the IT is expensive and outages are costly, monitor power quality continuously rather than waiting for a breaker to find the problem for you.
5. Power and Cooling Must Be Planned Together
Every watt delivered to IT becomes heat that has to be removed. Above roughly 30 kW per rack, air cooling is no longer viable, which is why direct-to-chip liquid cooling is now standard for GB200-class systems. ASHRAE's TC 9.9 committee added a high-density (H1) class to its thermal guidelines and, in 2024, published a technical bulletin on liquid cooling resilience covering coolant distribution unit (CDU) demarcation, thermal inertia for sudden load changes, and transient modeling.
What this means in practice: cold plates move the bulk of GPU heat to a CDU, but 10–20% of the rack load (memory, NICs, optics, power conversion) can remain air-cooled, so the room still needs air handling. CDU placement, coolant supply temperature (typically around 25–45 °C), flow balance, and leak-detection routing all have to be settled before the rack arrives. The fan-out from each switch to the servers - the MPO/MTP breakout cabling - should be routed deliberately so it never sits in the path the cooling depends on.
Do not approve power capacity without validating heat rejection. Cooling that cannot remove the load is the single most common reason high-density power capacity becomes stranded and unusable.

6. Limited Visibility Makes Capacity Planning Risky
Room-level or UPS-level monitoring hides exactly what matters in an AI hall: per-phase imbalance, localized overload, rack-level spikes, branch-circuit constraints, degraded redundancy, and stranded capacity.
What this means in practice: intelligent rack PDUs with per-outlet metering, branch-circuit monitoring, UPS telemetry, and DCIM integration let a team answer three questions in real time - how much capacity is in use now, where the risk is, and how much additional AI load can be added safely. Without that granularity, capacity planning is guesswork, and the first sign of a problem is a trip.
7. Scalability and Grid Constraints Slow AI Deployment
AI growth now outpaces traditional planning cycles. Even with floor space, a site may lack the utility, UPS, distribution, or cooling capacity for the next GPU generation. With data center demand rising about 15–17% per year, utility interconnection lead times in constrained markets have stretched into multiple years, which is why some developers are turning to on-site generation and battery storage.
What this means in practice: design for phased growth instead of a single hardware generation - modular UPS, expandable distribution, busway-based capacity additions, standardized rack power blocks, and clear redundancy and trigger points. The objective is usable, deployable, maintainable capacity over time, not the largest possible day-one system.
Traditional vs AI Data Center Power Design
| Area | Traditional Data Center | AI Data Center |
|---|---|---|
| Rack density | Moderate, predictable (often under 10 kW) | High and rising fast (100 kW+ per rack possible) |
| Load behavior | Relatively stable | Dynamic, bursty, synchronized |
| Planning model | Room-level or row-level | Rack-level and cluster-level |
| UPS priority | Capacity and backup runtime | Capacity, redundancy, and transient response |
| Distribution | Fixed or slow-changing | Flexible and expansion-ready |
| Monitoring | Room, UPS, or rack level | System, branch, phase, rack, and outlet level |
| Cooling relationship | Often planned separately | Coordinated with power from the start; liquid cooling common |
| Main risk | Insufficient total capacity | Stranded capacity, overload, instability, thermal limits |
How to Plan Power Infrastructure for High-Density AI Racks
Step 1: Define Rack-Level and Cluster-Level Demand
Start from the workload and hardware plan. Estimate the draw of each rack, each cluster, and each deployment phase, including GPUs, servers, networking, storage, and rack-level power gear. Use realistic growth assumptions - AI hardware turns over quickly, so day-one load is the wrong design target.
Step 2: Check Upstream Capacity and Redundancy
Walk the full path: utility service, switchgear, transformers, UPS, distribution panels, busway or cable, rack PDUs, branch circuits, and A/B feeds. Confirm the system supports both the expected load and the redundancy level under maintenance or fault conditions, not just in normal mode.
Step 3: Match UPS Architecture to AI Load Behavior
Look past total kW. Evaluate transient response, scalability, redundancy (N+1 or 2N), partial-load efficiency, battery runtime, parallel operation, and monitoring. Modular UPS is useful when the cluster will expand in phases, because it adds capacity without oversizing on day one.
Step 4: Choose Flexible Power Distribution
High-density rows usually need more flexibility than static panel-and-whip designs. Compare traditional panel distribution, overhead busway, high-density rack PDUs, dual feeds, and intelligent metering. A new AI hall often justifies busway sized for future density; a retrofit may be constrained to existing panels.
Step 5: Coordinate Power and Cooling Before Deployment
Validate cooling technology, airflow path, liquid cooling requirements, CDU location, coolant temperature and flow, floor loading, service access, and leak detection before installing racks. This avoids the classic failure of having enough electrical capacity but being unable to run the rack at full load.
Step 6: Build for Phased Expansion
Treat the power system as a roadmap. Define day-one capacity, expansion capacity, trigger points for UPS or distribution upgrades, monitoring thresholds, redundancy requirements, and budget stages, so engineering, operations, and procurement share one plan.
AI Data Center Power Planning Checklist
| Layer | What to confirm | Common failure point |
|---|---|---|
| Utility & switchgear | Confirmed interconnect capacity and a realistic energization date | Multi-year lead times in constrained markets |
| UPS | kW headroom, transient response, redundancy, partial-load efficiency | Sized for steady state, not millisecond load steps |
| Distribution | Busway/PDU ampacity; A/B feeds sized for the failover case | Each feed sized for N instead of the full redundant load |
| Rack PDU | Per-outlet metering, correct plug and breaker rating, phase balance | Branch overload before the cabinet is physically full |
| Cooling | DLC/CDU capacity, coolant temperature and flow, residual air load, leak detection | Power approved without validating heat rejection |
| Cabling | Fiber trunk and breakout routing kept out of airflow; service access preserved | Cable congestion blocks airflow and maintenance |
| Monitoring | System, branch, phase, rack, and outlet visibility; DCIM integration | Stranded capacity and imbalance invisible until a trip |
| Structural | Floor loading for 1,300 kg+ racks; door and aisle clearance | Rack cannot physically enter or be supported |
What to Look for in AI-Ready Power Solutions
Modular UPS. Worth it when the deployment grows in phases; it adds capacity and simplifies maintenance without paying for unused kW on day one.
High-density distribution. Busway or other flexible systems pay off in fast-changing rows where racks are added or relocated, and where dual feeds and safe maintenance matter.
Intelligent rack PDU. Per-outlet or per-rack visibility lets teams catch imbalance, prevent overload, and plan capacity accurately. This is the layer most often under-specified in AI builds.
Power quality monitoring. Look for visibility into voltage, current, power factor, harmonics, phase balance, and load trends, so issues surface before they become outages.
DCIM integration. Connecting power data with thermal data and rack utilization is what turns monitoring into capacity planning. When networking is part of the same build, an engineer's MTP vs MPO selection guide helps keep the fiber side of the rack as deliberate as the power side.
Common Mistakes to Avoid
- Planning only for total facility capacity. A site can have enough megawatts and still fail at the rack. Check rack-level and branch-level limits.
- Treating cooling as a later decision. Cooling planned after power is the leading cause of stranded capacity.
- Ignoring dynamic load behavior. Design for transient response and power quality, not average load.
- Under-specifying monitoring. Limited visibility means slow troubleshooting and unreliable capacity planning.
- Building a rigid architecture. AI hardware evolves in months; a fixed design becomes a bottleneck before the facility reaches end of life.
FAQ
Q: How much power does an AI rack need?
A: It depends on the platform, but the reference points are concrete: a general-purpose CPU rack draws up to about 12 kW, an air-cooled H100-class rack around 40 kW, and a fully configured NVIDIA GB200 NVL72 roughly 120–132 kW. The 2026 roadmap points toward 240–600 kW per rack.
Q: Can existing data centers support AI racks?
A: Some can, but many need upgrades. The limiting factor is usually rack power, UPS capacity, distribution, cooling, floor loading, or monitoring - not total facility power. A full power and cooling assessment is required before deployment.
Q: Do AI data centers always need liquid cooling?
A: Not always. Lower-density AI deployments can still use optimized air cooling. Above roughly 30 kW per rack, air cooling is no longer viable, so GB200-class systems use direct-to-chip liquid cooling, typically with a CDU and facility water in the 25–45 °C range.
Q: Why do AI workloads affect power stability?
A: AI training synchronizes large groups of GPUs, which ramp up and down together when jobs start, checkpoint, or change phase. These coordinated swings create fast power transients that stress UPS systems, PDUs, and upstream distribution.
Q: What UPS is best for AI data centers?
A: There is no single answer, but for AI loads the deciding factors are transient response, scalability, redundancy, and partial-load efficiency rather than total kW alone. Modular UPS suits phased clusters because capacity can be added as the deployment grows.
Q: How do you avoid stranded power capacity?
A: Validate cooling before approving power, confirm branch-circuit and PDU capacity at each rack, and monitor at the branch, phase, rack, and outlet level. Most stranded capacity comes from cooling that cannot remove the heat, or from branch limits that are invisible without granular metering.
Q: What is the role of intelligent rack PDUs in AI data centers?
A: Intelligent rack PDUs provide rack-level and outlet-level visibility, which lets teams track load, catch phase imbalance, prevent overload, and plan capacity accurately. In high-density environments, that granularity is what makes safe expansion possible.
Q: What is an AI-ready power architecture?
A: It is a scalable, monitored, redundant system that delivers reliable power from the utility source to high-density GPU racks. It typically combines appropriate UPS capacity and transient response, flexible distribution, intelligent PDUs, power quality monitoring, and cooling coordinated with power from the start.
Final Takeaway
AI data center power design is not about adding more electrical capacity. It is about delivering usable power - safely, visibly, and reliably - to racks that can draw more than ten times what legacy infrastructure was built for. Plan from grid to rack, coordinate power with cooling, monitor at the branch and outlet level, and design for the next GPU generation rather than the current one. Before deploying, assess rack density, distribution paths, UPS transient performance, power quality, monitoring, and cooling together. A power system built that way does more than prevent outages; it lets AI infrastructure scale on schedule instead of stalling at the first bottleneck.